Part 4 of 4 in The Brilliant Stranger, a field guide to LLMs, explained like you run a business.
Last time we fixed the book. This time, the last question in the series, the one that decides whether the rest matters.
“How does it know what to look at?”
A brilliant expert behind a door, a well-built book, and a limit on how many pages fit through. Someone still has to pick the pages for this question, right now.
The wrong picture: retrieval is a search box
Most people assume the assistant outside the door works like search: find documents with matching words, slide the top few under. That works about as well as answering a customer’s email by searching your inbox for the words they used. You’ll find something. Probably not the thing.
The better picture: a chief of staff
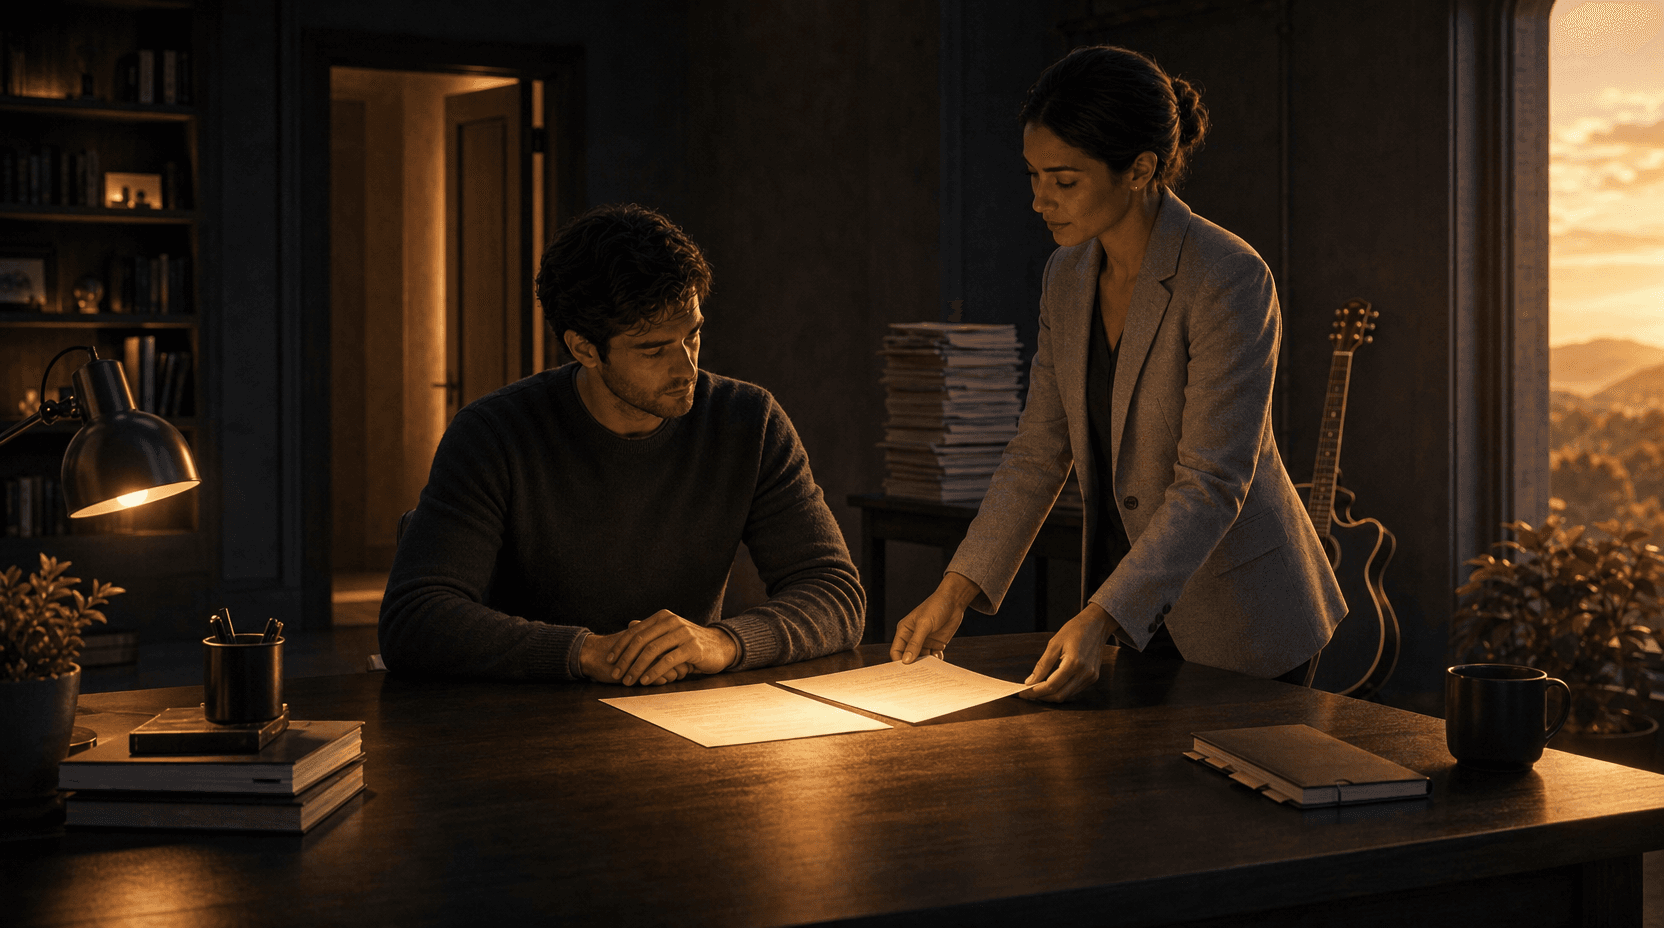
A good executive doesn’t read everything. Someone prepares them, and that person is the chief of staff. Before every meeting, they decide what lands on the desk: not everything that mentions the client, but the two pages that matter today. They pull numbers live because last quarter’s report is already wrong. They know the desk holds five pages, not fifty, and leave things off on purpose. If the executive asks for something that isn’t there, they go get it.
That’s the whole job: deciding what a very capable person gets to see, so their capability lands on the right thing. The assistant from post one is that role, done well. Retrieval is what it does. Judgment is what makes it good.
What the chief of staff actually decides
Selection by task, not keyword. “Can we offer this discount” needs the discount policy, this account’s history, the approval rule from March, and the live number on the deal, not every document containing the word discount. Start from what the task requires and work backward to the sources.
Ranking, and dropping. Five pages fit. Which five? And which forty-five stay off, because every unnecessary page dilutes the ones that matter.
Live versus stored. Policies, definitions, and how we do things belong in the book. Inventory, pipeline, and today’s date never do, because they change hourly. For those, the chief of staff goes to the live system. That’s what the errands from post one are for.
Freshness. The book says when each page was last confirmed. A chief of staff reads those dates and treats a two-year-old page differently than yesterday’s.
Testing its own work. When an answer comes back wrong, the first question is not “why did the expert get it wrong” but “what was on the desk.” Check retrieval separately, with its own questions and expected pages. A wrong page chosen confidently is the most common failure in the system.
The thing this has been building to
Step back and look at the four posts. The model is an expert behind a door with no memory and no window, and everything it knows about you arrives on pages. It’s also a guitar, already tuned, and you don’t retune it for your business. The pages have to be built for the reader, not inherited from the shared drive. Someone has to choose which pages, for which task.
The room, the door, the book, and the chief of staff are one system. The industry calls it the context layer. It sits between the model and your business, and it’s where your AI stops being generic and becomes yours.
It’s also the part nobody sells you with the model. The model comes from a lab. The context layer is built per company, from your knowledge, your systems, and decisions about what matters. Swap the model next year and the layer stays. Skip it and the best model in the world is an expert with nothing on the desk.
What this means for your business
Put the context layer on the org chart. Someone owns the book, someone owns selection, someone tests both. If nobody owns it, the shared drive does.
Keep it independent of the model. Any expert should be able to sit behind that door. Your book, selection rules, and tests survive the model swap untouched.
Measure the desk, not the expert. Track what was selected for real questions and whether it was the right two pages. That number improves. Model benchmarks won’t.
Don’t retune the guitar. Hand it the right chart. This series has been about what that takes.
This is the work we do. If you’re wondering what’s on your AI’s desk, reach out.